[1] https://ballotpedia.org/Fact_check/Is_the_death_penalty_more...
Also
1, this should have been released long ago cause many of these people are already dead.
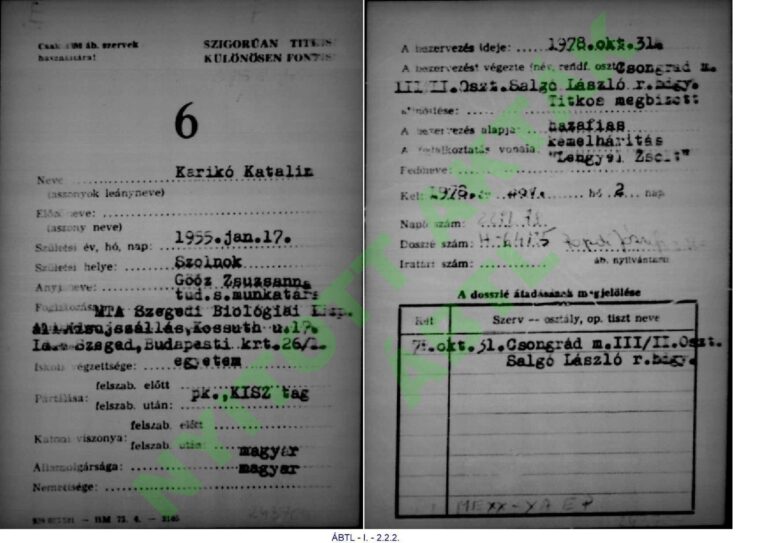
2, they only released the official record of the informant. Their background, who contacted them (from the secret police), when they were approached etc. But there is nothing about actual reports, like _did they do anything at all_ or not.
Even the Nobel Prize winner (2023) Karikó Katalin has a record on her yet she already wrote her autobiography years ago mentioning this, how and when she was approached and she didn't report anything at all. Now everyone have to decide on their own what to believe or not.
https://szegeder.hu/wp-content/uploads/2026/11/6c145795-f972...
a bit of context: I’m a product designer, and this was my very first open source project. I made it purely for fun, here’s where it started: https://x.com/saragordic/status/2098916110787916219
screenshots: I added the little video now; you can see many more screenshots on X, a lot of ppl shared their own
trust: totally fair; if you’d rather not run my binary you can build it yourself with the steps in the README.
the “send it to your coding agent” install line: that’s for ppl like me :D
I’ve learned a tooon by open sourcing this; thank you all for the feedback!!
> The more an article would benefit from photos, the less likely it’ll have them.
Love the idea btw, reminds me of a similar app that added xmas light to the dock.
Even tepid regulation will destroy the "our TIA is the entire observable universe due to the potential of self replicating AI probes so we totally deserve 10 trillion dollars in investor capital" trade
Sobriety the following day,
$8,000 for a video card,
Empty boxes on Christmas day.
Can't even rhyme without AI anymore.
I saw a similar thing some years back: playlists I had created began to be missing videos.
Been scraping ever since…
> This is the only yt-dlp wrapper that allowed me to properly maintain the Playlist structure to any extent
I have the same requirement and it's possible to do it with the default yt-dlp:
yt-dlp --embed-metadata --parse-metadata "playlist_index:%(track_number)s" "PLAYLIST_URL"
Many from my generation, who grew up during an era of information scarcity, have huge stashes of hoarded data. But what can we do with it? There is no way to legally share it, so we take it with us in our graves.
EDIT: Many good comments, but they all suffer from one blind spot, so I answer here instead of individually.
A lot of content is only legal because it is on YouTube (or any other platform that has deals with the content industry). Sure, we can share illegally in a way that is obscure enough that no one gets sued. But what help is that, eventually it will get either popular and sued out of existence or forgotten and fade.
Then there is old content that is not legally shareable at all, like old game ROMs. Plenty of millennial stuff there but the Gen-X world is already half forgotten.
Cooyright is just too long and too unreliable. What we need at least is exemptions from Copyright for archivists, otherwise a lot of stuff will simply be lost in the coming decades.
There's videos from ~15 years ago that I consider gone for good - lost to the great copyright apocalypse - having been unable to find them anywhere on the today's internet.
See https://www.cnbc.com/2026/11/04/data-center-ballot-measures-...
Stock volatility is typically clustered. So, we can't make this type of claim. Just like this statement is flawed: Chicago experiences below freezing weather 10% of the time, so every 10 days you see below freezing weather.
That's newsworthy, but also not extremely unusual.
The more interesting detail than nasdaq overall is just what sectors are having bad days and how concentrated that is. Seems to be predominantly AI companies, which is very relevant to the HN crowd.
His wife is chief of staff to Dario isn't she? Not saying this guy isn't smart but let's call a spade a spade here.
It's just not interesting to me. I'm sure most of us here have fixed little annoyances in our lives with AI at this point. I could write a post about how I forked newpipe to add features I wanted but I doubt anyone would care because they can just do that too.
I know the world is different now. I'm just crying about it is all.
We're just counting down to being unable to exist without a smartphone on your person at all times. What a dystopia.
I suppose if people started writing lots of code that crashed on error in Rust some enterprising developer might improve the function to always return a non-error value and set it to ‘*’ in error cases.
Does anyone know why musl does this? Are they the only C library that behaves this way?
For a C library that famously tries to adhere to POSIX as much as possible, this seems like a crazy choice. From POSIX standard:
Upon successful completion, crypt() shall return a pointer to the encoded string. The first two bytes of the returned value shall be those of the salt argument. Otherwise, it shall return a null pointer and set errno to indicate the error.
https://pubs.opengroup.org/onlinepubs/9699919799/functions/c...
To the extent that systems that are configured in the vulnerable manner exist in the wild, I’m surprised they weren’t exploited years ago by trivial ssh bots.
P.S. Wow, I’m reminded of just how awful traditional UNIX-y C APIs and code are.
P.P.S. The musl code in question is nuts. The API it implements is awful. Seriously, here’s the manpage:
https://man.archlinux.org/man/crypt.3.en
You can’t call this function correctly. sshd’s “fix” is basically to assume that a too-short return is an error return instead of a success return.
PAM is also awful, but this is worse.
PasswordAuthentication=no
I suppose if people started writing lots of code that crashed on error in Rust some enterprising developer might improve the function to always return a non-error value and set it to ‘*’ in error cases.
crypt() returning `*` is insane especially since these kinds of sentinels are all over /etc/passwd
Does anyone know why musl does this? Are they the only C library that behaves this way?
For a C library that famously tries to adhere to POSIX as much as possible, this seems like a crazy choice. From POSIX standard:
Upon successful completion, crypt() shall return a pointer to the encoded string. The first two bytes of the returned value shall be those of the salt argument. Otherwise, it shall return a null pointer and set errno to indicate the error.
https://pubs.opengroup.org/onlinepubs/9699919799/functions/c...
MCPs don't really need this level of technical explanations (it's basically just a REST API with standardized endpoints for discovery aimed at agents), and AI agents really do lack in the taste dimension when it comes to these things.
But I agree LLMs shouldn't have such an anti-feature.
Classic/recurrent examples for me are:
1. Ask Claude to copy code from a more complex codebase that you own (like a monolith) and ask it to copy code to a separate codebase, like you'd do when extracting a service into a new repo, and it'll make significant changes to how the code works to pacify it's anxiety with copying code
2. Ask Claude to build a new complex agent in a new codebase, and it'll try replacing asks around using LLMs as a judge/advisor with regex/other code based checks, to the point that the end-result will likely not work outside specific test criterias. I haven't figured out the reason why it does this. I think it might be anti-training, but it's interesting to see.
Other than that, the Common Lisp ecosystem is doing well thank you very much. Many contributors to SBCL, regular contributions to the important ecosystem libraries, vivid projects (Lem), new editors (mine) and plugins (OLIVE), some companies picking Lisp and somehow supporting the ecosystem (hosting conferences, contracting implementors). https://github.com/CodyReichert/awesome-cl/ · https://github.com/azzamsa/awesome-lisp-companies/ And yes, new vibe-coded projects too. Some are useful (ICL, cl-tuition…), some reinventing the wheel (badly) went nowhere. For some, we'll see.
As an example, a black hat doesn't get 70% of web sites from one shared bug in PHP. They need to target specific sites, and the exploit isn't likely to work in very many other places.
one SKU more is really not that much overhead for keychron if you look at their catalog
Yes, terrestrial light pollution has been the number one problem since we invented electric lights, but satellites and terrestrial light pollution are both separate problems with different effects and different coverage. E.g. even though light pollution is much more harmful, you can escape it with a short drive, even if you live in a densely populated region. You can't escape the strings of satellites.
Separately: "Shortly after sunset" is a downplay. It can be hours. But in any case, it's the time when the vast majority of stargazers are looking at the stars (with their eyes).
Satellites have the same awkward sociopolitical energy infecting them as all tech does nowadays. But remember: There is absolutely nothing wrong with being upset about the effect of these satellites, just like there is absolutely nothing wrong with being upset about the effect of electric lights. You can certainly get a lot of mileage out of weighing this against the consequences of having much fewer satellites, and that's exactly where all the argument should be occupied. That they affect the night sky, which reasonably annoys many people, is just a fact.
I remember thinking when I was a child how exciting the future was going to be. I had a bunch of these books talking about space and ships and stuff. Well, the future lived up to billing. We got there.
Satellites are only visible shortly after sunset and before sunrise, known as astronomical twilight.
If the images in the photograph upset you and you think our night sky is ruined, the thing that kills it the most is light pollution. Flood lights, parking lights, and street lights that don’t direct light down to the ground make viewing much worse than satellites for everybody.
It’s just as easy to capture incredible images of the night sky, even during astronomical twilight, with image processing. Here’s photos I’ve captured in my driveway in the SF Bay Area: https://bradgessler.github.io/observatory-blog/observations/
I captured said images with an Elixir software stack I installed on a Pi and hooked up to my telescope. It’s open-source at https://github.com/bradgessler/observatory for those who are interested. I hook Claude up to it and it runs observations for the night, processes images with deterministic tools, and publishes them as the night progresses.
The photographer made a really neat picture, but Kottke is presenting it with a headline that suggests its something else, and generally not giving enough context (mostly just blockquotes).
Even if I were to be as charitable as possible to your interpretation, "mendacious" is way too strong a word, and implies an unreasonable bitterness.
This is less an "image of our satellite-choked night skies" and more "a completely mendacious image produced using Photoshop".
I'll also note the frame rate issues in Conker were mainly down to raw RDP fillrate issues, which was for sure the weakest part of the N64 hardware, it could draw beautiful triangles (for the time) but oh so so slowly. There was a decent amount of speech during gameplay using the RSP mp3 codec. The cartridge size was still an issue, 64Mb got a good amount of mono speech but was still very much at a premium.
Things are crazy now. Our TVs snapshot the stuff we watch; our telephones, watches, and TVs are constantly listening what we say; our PCs have undocumented "remote administration" devices that we can't opt-out; every internet service out there is stealing every data that it physically can and selling it to a long list of organizations, including some military ones...
Many ISPs in many countries are forced to do this for certain enforcement action that gets put upon them by their respective states for things such as age gating, censorship, monitoring, it varies state by state.
And to be clear this is in no way an endorsement of the practice, and I am confident no ISP WANTS to do this.
I am speaking here as the owner of a UK ISP (who does not currently do this).
But their DNS responses have latency spikes every couple of minutes of 1-2 seconds that was driving me crazy. I simply enabled DNS over HTTPS in Firefox and everything feels so smooth now.
I have no idea how my coworkers seem to be so insensitive to it.
I suppose the answer is politics rather than technology: Get enough people together to make a rule against it, and at least it will become niche.
Maybe I'm too optimistic, but personally it would lower the burden on me so much to have a curated list of *awesome* projects.
The fact that another person has taken from their time, so the hundreds or thousands of people reading this list don't have to do the same amount of investigation to figure out if a project is truly awesome, is in itself awesome.
AI suffers the same problem Search Engines had: you cannot ask about something you dont know. Thats why monthly magazines were great: they pushed" knowledge to us so that we learned things we didnt know existed.
Recently, thanks to AI being this cheap and accessible, the amount of shitty PRs quadrupled if not more. And the worst part? Agent doesn't care about the checklist at all and re-writing the PR body with bunch of nonsense that we maintainers need to read, understand, and evaluate. I started keeping the score for the most shittiest PR based on how soon after the first commit made they open the PR. It was 11h, then 10h, and now it is 6h. How on earth a 6h old repository with zero user is considered "awesome" I don't know, but people should stop prompting their agents to create 10s of these PRs every day.
Yes, there's always an alternative: stop maintaining these lists. I don't think it's a viable option either. Sometimes you start using a new piece of tech and want to have access to somewhat curated list of resources that might speed up your understanding. There's still a bit of value to keep them alive and it's dying out bit by bit (literally) every time someone mass-creates these spammy PRs.
Thanks for reading my unsolicited rant.
I would rather hear from users of software and their opinions, otherwise I can't take seriously something ostensibly curated for quality. In my experience such lists serve better as a way to discover new projects using eg. some framework you're interested in, if they're maintained (which is still valuable).
Thing is though, for software, sometimes things can just be done. If a perfectly good piece of software hasn't been updated in years because it hasn't needed to be updated, then let it sit, ensconced in stone. The problem is it's hard to tell the difference between that, and something that needs maintaining but hasn't been.
If you were lucky, there was a tutorial how to do X. But requires tool Y. Where do you get Y? Here it is on some apache indexed site! Oh, I just installed Sp0rk3h. Well, time to reformat and reinstall Windows XP. Good thing I partitioned my 40gB HDD
The learning curve for Photoshop 7, when there are 0 resources was pretty tough. I remember how proud I was when I figured out how to make an animated gif. Hammer editor (Was it called Hammer? to make maps for Half-Life engine games like Counter-Strike), There was an editor for creating an archive of images. was it a .WAD archive?
That kind of self-directed learning without hand-holding, I think, is not a bad thing
Another one is Cmd+H for hiding an app. People often minimize the current window to see the next app underneath, while hiding the current app is much more elegant and creates a lot less friction for restoring it later.
Which of these hidden champions did I forget?
So I guess a comparison between TextEdit and Pages doesn't make too much sense probably, they're really different things.
They restricted wage growth too much for too long under Intel (despite being the only growing business unit), so the people with the valuable experience moved elsewhere. The Agilex line-up finally looks to be in the place it should have been 3 years ago, and it seems like they brought in a good marketing team following the Silverlake acquisition, but they still fall in this weird middle-ground now selling "performance-per-watt", which is a hard sell when most engineers optimise for the extremes. If I'm just need a bridge or some glue-logic, I don't need a device which will singe my thumbprints off while doing that. Generally, if you want better performance, AMD does an excellent job, or if you need low power consumption, Lattice is like 4 or 5x lower or more with just enough fmax and IO to be dangerous. If you look read Lattice's shareholder briefings, they're running away with the low/mid-range devices up to ~500k LUTs, and AMD is dominating anything 1M+. I couldn't help but laugh the other day when I saw an Intel reference design with a Lattice MachXO5-NX on it. Look at pretty much any datacentre rack now, and you'll spot 4-64 Lattice devices, when it used to be MAX10s top to bottom. Everything else is swept up by AMD.
For Altera, Agilex 9 (ADC and DAC converters integrated with an SoC FPGA) is probably their most interesting device, but that customer base is limited - basically comms and maybe radar with some weird and wonderful optical or quantum compute applications. I've heard friends of mine in the industry say very good things about it, but RF is not my strength so I can't comment.
In all honesty, they've got an insane fight on their hands to regain the market share. They canned their low end road-map when Sandra Riviera came in (as a classic Intel VP would do) and put all their eggs in the Agilex 7 basket for a long time. They've got Agilex 5 now (and Agilex 3, which is just the bottom SKUs of 5 with it painted over by marketing to fill the gap), which is great for vision applications, but only because they had a fantastic video and vision IP team who last I heard have left for ARM.
I hope they pull it back, as I loved the people there and it had a great culture, but it's been awfully mismanaged for a while and I question how easy it will be to pull it back considering the monopolies and duopolies that are appearing in the semi industry right now.
That's not even a paper launch at this stage.
Claude Fable is now good enough that I should be using it. The latest Claude version is said to be comparable to a mid-career graphics programmer, which is about what I need. Six months ago it wasn't good enough to use for such work, and probably would have made a hash of my code. There's been progress.
But Anthropic's business practices are scary. They have a reputation for cancelling accounts for random reasons, offer rather bad terms, and have no customer support. I have a strong aversion to services with a reputation for cancelling services arbitrarily. They will apparently cancel based on their system's guesses as to what you're working on. Sometimes they guess wrong. What I'm doing (metaverse clients) is so far out of the mainstream they may guess wrong.
I'm currently stalled signing up for Claude because their verification email system can't get to my inbox. (Some problem with their using Constant Contact, a spam system, to send transactional emails to my own domain, which, long ago, I had blocked at the Constant Contact end. I think. The verification email never touches the inbound mail server.) It's very important to Anthropic that you sign up with the "right" email address, and it may not be possible to change it, so using some disposable address is not a good idea.
Suggestions?
I cycle between 4-5 work projects and 2-3 personal projects. Every night I tell me agents I'll be going to bed and to not ask questions and keep going. I've always loved building things, but this feels more like an addiction than healthy sometimes.
They're not all done, and half the projects I bench, but this is where my personal projects live. https://wooten-labs.com
2) No.
3) None.
4) No.
5) No.
I'd say the biggest trick is just to tell it what complete looks like. Be very specific about what you want it to come back with once it's done. That gives it a good idea what the goal is. It'll automatically create subagents and all that stuff. Although if you have money to burn and you're doing something large, you can tell it to just go wide or boil the ocean.
Also, make sure you're working on at least five different things. Otherwise, you're sitting around for one agent.
These are relatively simple statistics. Some are even trivial. I don't see why it requires any people at all.
It wouldn't even have to be done by OpenAI. Given a list of vulnerabilities, it wouldn't be too hard for third parties to collect these statistics.
Yes, openbsd has not had a torrent of bugs found, but I would say that the vastly bigger reasons for that are: 1) orders of magnitude people care about burning tokens and money to find the bugs in an OS almost nobody uses, and 2) it's simply much smaller. Can't have Bluetooth bugs if you don't have a Bluetooth stack.
I've pointed LLMs at obsd stuff, and even the simplest code, e.g. cat & find, had bugs and buffer overflows.
OpenBSD also has a poor patch tracking system, since they're still on CVS. A patch has an extremely good chance of just falling through the cracks. Security or not.
So no. Nobody can write safe C. Not hobbyists, and not "those evil corporations".
- What subsystems are affected?
- What's the median age of the vulnerable code? Is more recent code stronger than old ones?
- What is the type of vulnerabilities found? Memory corruptions, logic bugs, race conditions, ...
This is an impressive result, but we need more info to understand how well this would translate to another codebase, and what lessons can be drawn from this experiment. Not every company has ~million dollards in tokens to spend.
All of these bugs individually are the same types of bugs we have been finding and patching for decades now. But we found a way to scale that far beyond what we had before.
It worked flawlessly but lets be honest. It's not like Claude checked random numbers with data slice and observed what e-paper did
I'm also pretty hostile to AI, but do recognize that these machines seem to be very good at finding exploits.
I'm sure there've been some some projects out there working to pentest/find cracks in OpenBSD via LLMs/agents/whatever-the-right-term-would-be...
But it is true the attack surface is much lower in OpenBSD on purpose, so hopefully it is overall more secure. But I'd like to see the numbers.
I've been working with a LoRa chip called the LR2021. I plugged a dev board into my computer and told Claude to reverse engineer it. He dissected it with a speed and level of efficiency I couldn't believe. Within a few hours, Claude was writing custom patches for a completely opaque patch RAM area meant only for the manufacture. I wrote about it here: https://beala.substack.com/p/your-node-doesnt-need-a-microco...
Speed requires a lot of code in the kernel, where that code can run fast.
There are kernels that do not have a thousand privilege escalation exploits. These kernels are smaller and much easier to check for bugs. But those kernels are significantly slower.
For many use cases, slower is not a problem. But for the large corporations who fund a lot of Linux development and use Linux in large data centers, every 1% slower can literally be millions of dollars worth of additional servers that are required.
OpenBSD shows that you can have a Unix security model without a thousand privilege escalation exploits. But OpenBSD is like 10% slower. So corporations won't use it because it would cost millions of dollars more per year and some of their software requires access that OpenBSD does not grant precisely because that access leads to security exploits (i.e. io_uring, eBPF etc. etc.)
You could also use like seL4, but that's slow too
So that's why. It's a business tradeoff between cost of servers vs cost of getting hacked, and cost of servers wins.
Absolutely, the front door has always been unlocked. We were previously protected by the economics of exploit detection favoring the developers, but now we have entered a new world.
The issues arise almost everywhere we look. It's frustrating because the user experience in edge systems has barely changed in the last fifteen years. We could have rode the advances in semiconductor manufacturing to embed more layers of protection such as CHERI while slightly slowing down the rate of performance improvements. Instead we have only marginally upgraded security and largely added features which the users scarcely notice.
I am hopeful about the long term prospects of formal verification, but having humans reviewing the proof statements and confirming they match our desired properties will take many years. Meanwhile, AI assisted hacking is an urgent issue. So we will have to delegate implementation, proof specification, and proof development to the AIs in the short term. Maybe that goes well, but who knows. Interesting times.
Is the kernel simply too complex to reason about? Is it an underlying flaw in the security model or language implementation?
Should we assume that all software is more compromised than the kernel?
I understand this work was based on a dated snapshot. Will there be any continuous effort, scanning new PRs as they land, to prevent new weaknesses from being added?
And we're hiring! https://openai.com/careers/search/?q=cyber
I did something on my site recently like that where you can click a hexagon and it turns into a robot and starts SLAM mapping the page, navigating around text elements carefully.
Were you initially surprised by how easy it was to get exact block size of individual characters and not just entire dom elements? That’s the part I thought was going to be the most difficult.
I think the argument is pretty simple:
- Plastic is bad (environment, microplastics, etc) - We should minimize it
That doesn't necessitate a "all the way to zero or don't bother" logic, which what you're saying reads as.
Coffee pods machines have been an environmental nightmare, great to see a growing trend that addresses this.
While I sympathize with the sentiment to eliminate plastic from the transport chain for anything ingestible, it's practically impossible in the modern world.
Simple is usually best; glass or ceramic pour over, stainless press, or even the traditional South American coffee sock[0]
[0]https://perfectdailygrind.com/2016/01/coffee-sock-old-school...
This summer was sunny and hot in Colorado, so every morning I'd make a jar of sun coffee. I'd leave it out through the day and overnight. The next morning I'd pull it in, filter it, refill it with grounds and water and take it outside again. It was cool enough to enjoy and really smooth.
In many cases you can’t find out who the owner is. There’s too many shell companies involved.
These firms don’t care about occupancy, they care about the resale book value.
Business tax rates are based on those property valuations.
There’s no chance the property companies will reduce the value of their portfolio to reduce burden for tenants they don’t care about.
Then you have foreign online retailers like Amazon and Temu able to use complex multinational tax avoidance schemes and fake products to undercut the high street.
How can you compete if Amazon can deliver a knock off from China, that you can’t legally sell, faster than you can stock a real one into the shop, and at half the price?
A lot that I see have extremely cheap-looking fixtures and little to no decor, and unlike virtually any other store, they stock what they stock, which is generally the same as every other vape shop, and don't even bother to fill out the entire space if it would hold more merchandise.
I assume some are able to negotiate lower rents in exchange for short term leases while the store is technically still on the market for a long-term lease, similar to a pop up store. A lot that I've seen could be shut down, with all the merchandise and equipment loaded into a UHaul, within a few hours if necessary.
Nail salons are similar. They really should have custom ventilation systems since they're working with paints and solvents and glues and nail drills/lathes, but this seems to not be enforced since they're seen as girly little spas rather than industrial workshops and are often staffed by poor immigrants.
Central planning is the status quo. That's essentially what zoning rules are, and why everything is such a mess. You want to open a shop and live above it? No, sorry, not zoned for residential; banned. Operate the shop out of your house instead? Haha, banned. What if your shop really doesn't need very much space at all, so something the size of a closet would do as long as it's in the right location? Nope, minimum unit sizes or similar, prohibited by law. And so on.
If they want to stop doing this that would be great, but if they're not going to stop doing it then having the rules be things like "no chains" instead of "no small units" would certainly be an improvement.
You're advocating central planning.
The real problem is that it's very hard to build stuff in the UK. This is a choice that the people have made and the status quo still continue until they choose differently.
Zero info on who the government hundreds of millions is going towards to help the problem (let me guess: a bunch of nonprofits who won't solve the problem).
A race to the bottom, but I wouldn’t blame Amazon. Large multinational chains were hollowing out high streets and making them less pleasant before online shopping.
As another comment said, councils and government should treat high streets more like public commons, prioritising independent businesses and making places distinctive.
What frustrates me is that even prosperous areas with new developments rarely make space for small businesses. Instead, we get “private equity” chain.
Ugh, one I saw recently was Bristol University’s new campus by Temple Meads. The wall between the campus and station could have been lined with small, affordable units for independent and student-run businesses. Would love to browse a few interesting shops or grab a decent sandwich before catching a late train. 23m for a new entrance but where are the opportunities. (This is based off the media announcements, not walked through there yet)
We've build our urban centers as places that prioritize cars over people, and we're suddenly confused as to why people don't want to spend time in them.
I'm a Frenchman but I hold no particular dumb grudge against the English, I actually like them, their style, their music, what I perceive as their refinement as much as their capacity to be hilarious, quick with the banter, overall good lads
so a few years ago, I booked a trip to London, then a train to Northampton cause I wanted to see the city where all the good shoe manufacturers are based (I own a pair of Crockett and Jones and enjoy other brands like Cheaney, Trickers, etc).
what a BRUTAL wake up call, what was on paper a thriving manufacturing town with rich history turned out to be a completely derelict place, with boarded windows in the main streets, beggars, dollar shops, litter absolutely everywhere and the signs that the golden age of the town is LONG gone. I don't know what happened there, recession, Brexit, I really don't know but I ended up taking the train back to London earlier than anticipated, completely shocked by what I saw
Really shows why companies salivate over people using these features.
A noteworthy proof of this is the failure of Amazon Dash buttons [1] that blindly ordered your consumables for you. Amazon gave away these devices essentially for free ($5 off with your first order, or some such offer), and people still didn't seem to have been comfortable to use it.
Amen, there's a worldview difference going on here, and it goes beyond comparative pricing of 2+ choices, and includes other error/reliability issues.
For example, they aren't too concerned with the reservation-cancellation fee when it schedules the wrong fancy dinner date, the restocking-fee for returning the wrong product, the difficulty of getting refunds for the wrong flight, etc.
If it messes up sometimes, well, that's just the price of convenience... but they're able/willing to put a much higher price on convenience than the median consumer.
Agents seem like they might be helpful for high-friction tasks, with a lot of data. But summoning Ubers and ordering food aren't really that.
Text is just not a good format for ordering things. You want to see pictures and just click on the options you want - we’ve had people paid 300k working on the optimal visual interface for this for probably 30 years, just trying to improve the sale rate 2%.
Agents are good for open ended problems which require stringing together lots of different data sources, which couldn’t be further from ordering food.
"You can call an Uber with a voice command"
"You can ask alexa to buy you things"
"Your AI will order food for you"
Seem like magical ideas that will remove friction and increase sales. Except that regular people compare 13 different options to pick the cheapest one. No one wants to see food appear on their doorstep followed by a bill they cannot pay.
The UX experience for basically all LLMs that I've interacted with is having the AI sneak in where I don't want it and end up taking 10 extra seconds to do what used to be a 0.1ms operation.
The worst place for AI is in search bars, yet that seems to be the first place every product manager wants to put it. I hate waiting forever to get results because AI is poorly searching in the foreground.
My budget app, for example: It’s not easier for me to ask the AI bot “show me all my transactions from McDonald’s” than it is to click on the search bar/payee filter and type “McDonald’s.”
But if I use the AI bot, I’m burning tokens.
Coding related have had massive step-up improvements over time.
The same cannot be said for image generation. If anything, I swear it's gone backwards.
It peaked with very early midjourney (like 2022), maybe follow ups with stable diffusion, and then with some of the nano banana models for actual editing. But overall, very lackluster in comparison to other areas.
It is entirely possible to prompt engineer away from that style, but that requires effort and knowledge that said average person does not have, so it's stuck in a feedback loop.
Like, I'm not even an artist, so I'm sure there's a million things I'm missing, but it's just so upsetting to look at. There's weird random reflections on things that shouldn't have reflections, the coloured light absolutely doesn't actually track through the stained glass onto any surface that makes any sense, light is coming from every which way, it's just... gross to look at for anything more than a quarter of a second.
And this is what they're using to hype people up for it. /shrug