The problem was, they had to sell their invention to other guys that had grown up with 8-bit micros and in the meantime had gotten very attached to their specific 8-bit encodings, so they had to make a lot of compromises: first 128 characters match ASCII; first 256 characters match Latin-1; alphabets encoded in order; codepoint-to-codepoint transcoding from any (reasonable) legacy encoding; throw out enough stuff to not need more than 2^16 characters. They were also racing against time, because in the meanwhile ISO was cooking up 10646, the Universal Character Set, built around ISO 2022’s teletype-inspired architecture of charset switching, and that only got killed because software vendors essentially declared a boycott and pointed to Unicode instead.
The result came out rather awkward as well as fairly expensive, and a lot of the promises needed to be broken afterwards anyway. But they’d have no users had they had done things differently. (Meanwhile, the UCS as initially conceived lacked such advanced operations as string equality.)
https://www.cnrs.fr/en/update/choose-cnrs-opportunities-scie...
It’s an app, not a system-integrated[1] screensaver?
> Installation
> Drag FakeDOS.app into /Applications.
> Double-click to launch. It installs itself as a menu-bar icon.
> Click the menu-bar icon to configure or start manually.
> After the configured idle time (default: 5 min), FakeDOS takes over fullscreen.
> Type EXIT to return to your real desktop.
> Cmd + , opens six pages of pure control: idle time, warp speed, the ghost writer, sound and more. The PC speaker can be silenced. Your co-workers cannot.
[1]: ScreenSaver.framework: https://developer.apple.com/documentation/screensaver
Standing in the hallways listening at different angles, as the article says, didn't help. No Fable in '05 either.
So I had to improvise. Got a ~1 meter stick and two headphones (every headphone is a microphone, even if it sucks as a microphone). Plugged them into the stereo mic port, and started recording in Audacity. The phase shift between L and R pointed directly to the source. Took about 4 or 5 beeps to get the sucker.
Turns out, it was hiding above the ceiling tiles in the garage. My wife still tells this story to all her friends as one of my biggest life achievements. Everything I shipped, the companies I founded -- pales in comparison to finding a dead smoke alarm
Our dog goes outside and hides in the lavender bush if a smoke alarm starts making a "I need a battery" noise.
So I went into this project with the attitude that I would like to solve this class of problem forever.
1) Move half the boxes to another room.
2) Listen for a beep and determine which room the beep comes from.
3) Take the boxes in that room and split them in half again.
4) Repeat until one box is left.
"With emissions from land-use change (such as deforestation) projected to increase slightly this year, total CO2 emissions are projected to be 43.3 billion tonnes in 2026 – up from 42.8 billion tonnes last year."
Total annual CO2 emissions are projected to increase by ~half a billion tonnes as a result of land use changes.
https://gml.noaa.gov/ccgg/trends/global.html
The Iran blip is clearly seen, but it's just that - a blip. Levels continue to steadily rise.
Fun fact, it was invented by Leon Theremin. The inventor of the Theremin.
[1] "Traffic Flow Estimation using LTE Radio Frequency Counters and Machine Learning", https://arxiv.org/abs/2101.09143
Oh well, there have always been ways to snoop on someone like that. Back in the day it was CRTs emitting measurable waves through the neighborhood, with some papers even going as far as restoring the displayed image through a wall. Nowadays it's fiber and WiFi, and those seem to be much easier to work with even. Plus everyone carries a device that is tracked by their mobile provider's cell network. shrug
At that point I will be able to have the fun of AR (gaming with paper toys or other papercrafts, displaying characters on a table for my tabletop RPG group, getting directions in a foreign city, identifying plants and insects just by looking at them, seeing where my cats are located through walls via their airtag collars) without any ads, without any data harvesting nor privacy concerns, and even being able to write my own custom apps or firmware mods. It will still be a toy rather than a necessary part of life like a smartphone has become but a fun toy nonetheless.
I agree with the article that AR glasses are not a great future, but I think [ e-display eyewear / screen spectacles / whatever we call them ] that are dumb and just display what you feed them, are great!
US Military costs ~$1T/year and the Pentagon hasn’t passed an audit in the last eight years, comparatively, but not a lot of similar complaints of that waste versus pensions for workers operating and serving a national public service agency.
https://www.militarytimes.com/news/pentagon-congress/2025/12...
Electrifying the USPS light vehicle fleet is expected to generate up to $4.3B in lifetime savings over the fleet lifecycle, similarly.
https://huffman.house.gov/media-center/in-the-news/electrify...
https://atlaspolicy.com/federal-fleet-electrification-assess...
I personally get a massive benefit from USPS being cheap, despite the fact that I send no mail. It provides a massive low-cost physical delivery network across the country, with service to every address. This is a benefit to me because it makes business and personal communication simple and reliable. If I need it personally, it's there. If I don't, I still rely on thousands of parties who do.
Your position is like claiming the interstate system is useless because you don't have a car, ignoring how all those goods your life relies on actually get to you.
By no means was I implying that the ability to profit means they did profit. Im just stating what the law was.
I was confused by this until I realized you are missing some logical steps in your (accurate) argument.
The 2006 law took away the safety net (ie the ability to charge whatever is needed to break even).
The “you can now make a profit” rule actually made it HARDER since it came with a price cap.
It told the USPS: You can keep any profits you make, but you cannot raise prices above the rate of inflation to get them.
This forced the USPS to absorb rising costs through internal efficiency rather than passing the bill to mailers
This isn't really accurate. USPS had a break even (not profitability) legal mandate since 1970-2006. They would adjust prices each year to hit break even. And that's what happened - they roughly broke even each year.
After a 2006 with broad bipartisan support, the UPS was able to make a profit (not just break even) but a price cap was added (to be reviewed every 10 years). They couldn't raise costs beyond inflation. A stamp to send to anywhere in the USA - anywhere (Alaska, Guam, etc.) - currently costs 82 cent. The postal union is against this, usps management is against this, and business mailers are for it. Dont you love all the ads USPS delivers you?
They have not been break even since 2007. They currently lose about $9B/year with $2.7BM being controllable and the rest largely being pensions, retiree health plans, and workers comp charges. Their core business (mail) has been declining for 20 years and no end is in sight. In 2020 they loosened the cap a bit (allowing USPS to raise prices). Business mailers tried to sue them but lost.
So this attitude that they should just lose a bunch of money and be backstopped by the taxpayer, when mail is less critical than ever, is an recent idea and is aligned with business mailer lobbying interests. It seems obvious to me that they should just go back to the break even mandate.
Just a visualization of zip codes. Start typing a number and it highlights the zip codes on a map. Mildly interesting at best, maybe someone will like it.
I really don't understand the justification for withholding operational data like this. We are trying to make the job of the USPS easier with these tools. It's a lot cheaper and faster for everyone involved if I can query the database while the customer is still standing in front of me.
It is great for governments to run responsible budgets, but this was such a unique constraint, it seems designed to strangle the USPS.
However, what I believe many are missing is that having a physical mail network that is accountable to the public good and our government is an advantage for many important situations that should not be dependent on the free market.
One of the features I would try to add at employers was address correction. The addresses API used to be free (became a paid service in August 2026). If you've ever seen a popup at on an order/address form which says something like "you entered X, but the Post Office recommends Y" (or similar words), then you've seen the results of the address API [1].
Notes:
0 - 2022 changes to the 2006 law let them stop prefunding 75 years ahead of time.
https://www.uspsoig.gov/focus-areas/did-you-know/what-did-po...
> To qualify for regular retirement, employees must have at least 30 years of service and be 55 or older; or 20 years of service and be age 60 or older; or 5 years of service and be age 62 or older.
https://en.wikipedia.org/wiki/Postal_Accountability_and_Enha...
I suppose though, as long as you let the polygons map has uncontained areas, where no routes currently exist, it's a doable task to draw polygons around the limits of every route network, as long as you don't mind that they may have lots of weird ragged edges.
what next paying for knowing street names or house numbers??!??
Can someone with expertise in govt data rights explain? Do any other US govt agencies sell data to the private sector?
FWIW if you're willing to deal with some 'fuzziness' and the occasional missing zip code that's commercial only, the ZCTA shapefiles are free and are close enough for many purposes: https://www.census.gov/programs-surveys/geography/guidance/g...
I especially liked "The Perfectionists: How Precision Engineers Created the Modern World" and "Knowing What We Know: The Transmission of Knowledge From Ancient Wisdom to Modern Magic".
But all of his works are great.
https://strandsagents.com/blog/introducing-strands-decider/
They lopped the head off an existing Qwen or Gemma model and used its torso with their new head.
If you want to make a ticket classification model, you don't need to train across many customers doing ticket classification, who might not want you to train on their data and whose data is impossible to obtain unless you already are a large company. Instead, you can train on a completely different task which forces the model to learn the syntactic and semantic structure of the English language — say predicting missing words in Wikipedia articles, which you can't do successfully without a good understanding of English — and then fine-tune that model on your specific task with much less data.
Because the initial task is so general, you can have one company do the expensive pretraining, share the base model, and then have everybody else just do the finetuning on their (small) proprietary dataset.
LLMs and models like Jev go one step further, letting you use them as classifiers with no training at all, with nothing but rules in the prompt. And with a few tricks, you can indeed use them to get pretty high-quality labels, which you can then distill into a fine-tuning dataset for a much smaller model.
I checked just for fun and there are actually a LOT LOT more than 92M tickets in the past year.
An issue in industry was that companies would not allow training on their data across customers. Understandably so, as SVM dimensions are readily interpretable given some thought. General purpose datasets were ill-suited too depending on the task.
So you'd start from scratch every time, annotate features like crazy, and often didn't have enough training data overall.
LLMs "solved" that by just ignoring the previous rules and training on everything, which lets the necessary world knowledge seep back in.
I'm sure we'll see many combinations of LLMs and regular machine intelligence in the near future.
With the LLM you don't even need a data scientist to train the model, you just need someone who can connect to APIs. And the LLM is fine with adding and removing categories. No retraining.
It makes the initial faces incredibly fast. Then it is slow and expensive to run, so once the system settles, it becomes the target for model optimization, e.g, a dedicated, or semi-dedicated model.
I initially thought of tickets as just customer support, or internal JIRAs, but the article mentions alarms, security findings, and capacity increase requests, so that makes the scale feel more plausible. Still surprising so many tickets go through the system.
— "Let's build efficient classifiers"
— "Forget about the silly classifiers, LET'S BUILD A MACHINE GOD"
— "Ah, that machine god is often too expensive and underwhelming. Let's build efficient classifiers"
[1] "Linnaeus: A highly reusable and adaptable ML based log classification pipeline", https://arxiv.org/abs/2103.06927
NOTE: the work was actually accepted at the International Conference on Software Engineering (ICSE) in 2021.
> Private: this provider does not train on prompts and does not retain prompt data.
So how come notion discovered that they actually stored the data?
> Upon analysis of the new data, we discovered that it included unattributable Notion AI chat transcripts
> As a precaution, we recommend that you treat this unattributable data as if it were exposed. If anyone on your team pasted sensitive information like passwords, API keys, or other credentials into Notion AI during this timeframe, we recommend rotating them right away.
Okay, so the actual impact is quite interesting: they did not notify you if they could not attribute the transcripts to you! You should really treat anything sensitive sent to Notion AI as compromised because they are not sure where these transcripts came from.
This is almost certainly an independent discovery/implementation of the same idea, there's really only one sensible way to do it. There are, of course, several non-sensible ways to do it as well, but...
Although if I were earlier in my career I'd be somewhat more worried about employment because of how horrifyingly borked the process is for anything tech related right now.
Whip cracks
Yeah.
I'm not going to claim to be any particular multiple developer, but as someone who has been doing this a long time and as someone who has received praise from coworkers and bosses alike for being very good at the job, I enjoy my job a lot less than I did a year ago (or anytime since I started doing it in the 1990s).
Don't get me wrong, being a Senior Agent Babysitter probably still beats flipping burgers or being a roofer (so it could be a lot worse) but agentic AI has really sucked a lot of the fun parts out of the job.
every 10x engineer needs a team of 1x engineers for the contrast and difference to be even noticable to even the good managers. put 2 of these in a team and watch the culture and productivity plummet. if you cant put the team ahead of you, its all a sham.
The gervais principle [1] isn't for nothing
[1]: https://ribbonfarm.com/2009/10/07/the-gervais-principle-or-t...
As a "10x" engineer I am not excited. I'm still working on projects with agents getting more done than ever, but I feel like software engineers has lost its soul for me. I don't really feel like I have a true understanding of anything anymore, I basically just spend all day making a set of small decisions or adjusting prompts to guide the agents down the good path. It used to be that I could close my eyes and visualize the code that I worked on--if there was a bug report I could often use that map to immediately know what the cause likely was. In meetings I could intelligently discuss various tradeoffs without having to refer back to anything. Now if someone asks me a technical question I basically have to forward it to the agent first, then interpret their response in light of my experience.
This is the real fear. We had a flood of engineers who entered the profession in the past 10-15 years who were decidedly average. No real interest in software development beyond "it's a cushy desk job, or better yet WFH job, that pays really well." No interest in whatever product was being developed by their company. Just show up, their PM assigns them a ticket to make a widget with a button, they use their TypeScript bootcamp skills to code up a widget with a button, ticket moved to In Review, job's done.
Now an agent can do that, and you need fewer of these types of people. Like, a lot fewer. Every engineer on your team who isn't a 10x-cum-100x engineer feels like a massive lost opportunity.
The "10x" engineers I know have never been more excited about their jobs. I'm really unsure what's going to happen to the average ones.
reading HN these days feels like constant gaslighting. this is so far from my reality that i wonder what folks who are saying this are working on
The death of SaaS could also be a thing in the (not so distant) future.
The problem is that software in corporations has typically been product managers at the front, software engineers in the middle, and QA at the end. Software developers who also have good product sense and do diligent QA are still needed. Programmers who treated their job as leetcode exercises are not needed anymore.
If it's just web then it's as crossplatform as vanillajs.
I say this bc I'd be genuinely interested in genuine crossplatform for my client audience of professionals and knowledge workers who, as it stands, are mostly (though not exclusively) Windows users and deserve nice applications.
"Between two operations nothing moves. Instead of sleeping until an animation finishes, the agent says clock +60000 or clock settle and reads the result. No timing flakes, no waits."
The other night I carelessly made an infinite runner game while watching TV and the feeling of sheer abundance quickly faded into a bit of depression. Without scarcity, nothing is really valuable.
He's been publishing his work at https://waitinggodot.in/
My younger one has been creating little things on a microbit using the block based environment online. He's enjoying it too.
The world has changed and we can never go back.
While it's nice that LLMs are getting better at arriving at the desired deliverable with fewer surprises (or broken things) doing it is not necessarily a sign that the model is actually smarter, just an indication that what you are doing is likely a well-trodden path for the model, the RL and the harness.
This really was more like a normal person had access to a game developer team (with artists and musicians) and had a custom game built based on interviews and playtesting.
Basically, I think it's okay to have a bit of fun playing AI-generated video games at your techie uncle's house, and their parents agree. And for what it's worth, Aiden drew every character and boss himself - the game was built from his drawings.
My nephews are otherwise very active, learning music, martial arts, and other sports. But when they visit, I let them play games in between other activities. My parents refused to let me play any video games at home, and I still think that was really lame. Video games are another art form to be appreciated - they just need to be enjoyed in moderation.
Generally, though, I worry about the future and the potential for cognitive decline that comes from having AI agents do everything. I don't have a good answer here, except that I suspect we'll have to intersperse AI use with periods of deliberate daily cognitive struggle to avoid decline.
The first thing I felt when I saw this post was concern on the impact of this type of thing on the mental development of children. For example developing specific skills like drawing, and general emotional skills like concentration and learning to be happy with their own skill level.
I respect it was a light post where your aim was probably to highlight something fun, but I couldn't see any note of what you thought about it.
What do you think about that? What do his parents think?
Opus 5.5: https://claude.ai/artifact/UuT7P936dU1XoPByYZ7xyD Fable 5.2: https://claude.ai/artifact/UszKFvuonWAT5psjMttAEg
There are some areas in which Fable is clearly better but subjectively the Opus 5.5 version feels more fun.
Both are one shots, Opus 5.5 was done a few weeks ago before they added "guardrails" around recreating games. Fable 5.2 changed some game mechanics despite my prompt asking for them to be the same as original game.
If VC money gets tight, they would have to issue debt, that pay interests. With a current negative EBITDA, their bond will be junk at IPO, paying higher interests and having a lot less market than AAA debt (e.g. Google has access to that market). Both things combined translate to "running out of cash".
[Sept 2001] https://www.latimes.com/archives/la-xpm-2001-sep-27-fi-50296...
"Exodus Communications Inc., which never made a profit since it went public in March 1998, filed for bankruptcy protection after losing customers in the collapsing Internet economy."
"Exodus, which runs 44 Internet data centers on four continents, listed $5.98 billion in assets and $4.44 billion in debts in Chapter 11 papers filed Wednesday in U.S. Bankruptcy Court in Delaware. The company operates so-called server farms that provide Web site services for businesses."
"The Santa Clara, Calif.-based company’s losses increased more than tenfold in the second quarter, and it fired workers as it failed to win new contracts fast enough to replace those it lost. Exodus counted Yahoo Inc. and AMR Corp.’s American Airlines among its customers."
"Trading in Exodus shares was halted before the markets opened Wednesday. The shares fell 33 cents to 17 cents Tuesday and have plunged 99% from a record $89.81 in March 2000."
"Analysts say Exodus, with eight different junk bond offerings totaling about $3.4 billion, ran up more debt than it could handle."
“We sacrificed profitability in exchange for growth and market share, over-expanding in some areas in advance of demand, not anticipating the decline as the dot-com bubble burst and the economy weakened,” Krause said.
"Exodus’ second-quarter loss grew on acquisition and restructuring costs to $583.4 million, or $1.05 a share, from $51.8 million, or 13 cents, a year earlier. Sales rose 79% to $318.7 million but missed analyst estimates. The company lost $256 million on sales of $818.4 million in 2000."
But the cost to add more power capacity is huge and highly variable. Just because oil is expensive today doesn’t mean the capex to pump more is justified.
Really what AI needs is large customers that will commit to large spend over the next 5-10 years. Without this AI companies are basically offering duration arbitrage of electricity. Not a good place to be; the finances will always look bad.
Unfortunately, the amount of capital required by the entire AI industry is enough that counterparty risk is now a concern.
The size of the pay difference is something you, as the prospective employer, have significant direct control of. It is within your authority to point the dial anywhere from "hard to find anybody because of the massive pay difference" to "easy to attract strong talent, while still saving money relative to what it would cost to attract the same level of talent in the US".
The Canadian business establishment will not come after you to break your knees if you offer higher wages than they do.
“I said they were the best engineers in Canada.”
(Quote from the BlackBerry movie)
Attracting strong talent in Canada is hard given the massive pay differences gained by moving south of the border.
The U.S. invented real-time gross settlement electronic payments with Fedwire in 1915 [1]. FedNow is the newest real-time end-to-end payment system [2]. It launched in 2023.
[1] https://www.federalreservehistory.org/essays/fedwire
[2] https://www.frbservices.org/financial-services/fednow-servic...
Germany is another first mover with decades old banking systems and standards. German banks also dragged their feet supporting SEPA Instant or they added additional fees so that barely anybody wanted to use it.
Then the EU stepped in with regulation: If you support classic SEPA transactions, you also have to support SEPA Instant for the same price (which is almost always free for retail banking accounts). And suddenly banks did.
The new mega-deduction recently announced [1] results in an effective 6% corporate tax rate, which is among the lowest in the world and certainly in the G-7. Things like the RTR are just one example among many of the efficient infrastructure that Canada is introducing to address a very long term productivity gap (the mega-deduction is another).
And, R&D conducted in Canada is always a current-year expense and never capitalized. And there is a refundable tax credit for R&D that works out to about 60% of engineers' salaries (in most provinces). And those salaries are lower than they are in the US (something that engineers in Canada have a right to complain about).
[1] https://www.canada.ca/en/department-finance/news/2026/09/gov...
Like all things from any government -- let's see how the rollout goes. But I am cautiously happy to hear about this.
Part of it is "the curse of good enough": the US has had good credit-card style infrastructure for over a century and digital infrastructure since the POTS days. Part of it is that we lost our appetite for anti-trust in the 80s. Part of it is that the price structure of this infrastructure has wormed its way into everything in a way that is difficult to undo without causing high-visibility inconvenience for low-visibility benefit. The good-enough is the enemy of the good.
> Outgoing transfers cost 0.75% of the transaction amount (minimum of $1, maximum of $30). SoFi does not charge a fee for incoming transactions.
> SoFi Plus members save 50%. They pay 0.375% of the transaction amount with a maximum of $15 (minimum remains $1).
* https://globalnews.ca/news/12142666/real-time-rail-payments-...
> The initial cohort of active RTR system participants includes: Wealthsimple, Questbank, Peoples Trust Company, Paramount Commerce, KOHO, DoBusiness.com™, Digital Commerce Bank, Bank of America,

Amazing.
It’s not clear what clicking yes does. Is it my entire drive and Gmail? Do I have to give permission per-file/folder/email?
So I click no. And it just gives me the popup again later
> Google Photos data is used to infer your interests, relationships to people in your photos, and where you've been, including by associating your face with corresponding location data and timestamps. This data is also used to do things for you, like look up your info or add items to your grocery list, and to improve Google services, including training generative AI.
How does that work exactly if the images aren't even real and are generated by AI? When Google siphons up these photos to help them train their AI, the AI is now going to make associations as depicted in that photograph?
That you really were with that person, in that place, in that situation, on that date? As some sort of a fact?
Can someone else create that image and just put it in their library and then have that become a fact on your behalf when picked up, analyzed and trained on?
Where does that all lead?
https://knowledge.workspace.google.com/admin/generative-ai/g...
So basically if you use consumer Gemini and specifically authorize the GMail app, for example, then it will sometimes use the GMail tool to load your mail from GMail, and that data (like all data in consumer Gemini) might be given to the human annotation pipeline.
This whole thing seems deeply stupid to me from Google's standpoint, although they've never been good at product management - there's _way_ too much nuance to what's going on and even if they aren't technically affected, this kind of thing will almost surely make their paying enterprise customers leery.
But it does explain some conversations with Gemini when I wonder why it's talking about particular things. Like asking it about consultation processes for changes to parks only to get a response that's uncannily tuned to the email I got prompting the enquiry.
No mention of I just read your emails etc .
The actual content is somewhat relatable but don't fall for the bait.
He's working 10 hrs. a day, just entering things into Claude, waiting, reviewing, and learning absolutely nothing.
At this point anyone who was truly passionate about programming, is just less and less motivated to become a better engineer.
In winner-takes-all markets, it becomes worth it. The utility of the marginal improvement doesn't actually diminish, in fact, it increases like a hockey stick. If you could pay 3x more in compensation to hire a 20% better employee, it's almost always worth it in knowledge work industries.
While they made, hands down, the best models, their 100x price for few percent better is completely made up, and I think it will end up bad for them
If you leave xhigh and max off.. you still get better performance than Opus 5.5 max
Opus 5.5 Max - score 59 - cost per task - $10.04
Fable 5.2 High - score 62 - cost per task - $9.08
Note: This doesn't really capture the reality of things like 3d design or electronics design, where the earlier models just can't DO any of it well. Maybe you can bandaid over some of the gaps with strong skills, etc. The newer models can just do things that were not possible at all. When you move outside of coding into the visual/spacial space, you'll feel the inflection point on those capabilities that are happening right now.
But perhaps the performance on real-world tasks will be more noticeable than on benchmarks.
Notably, in order to achieve a specific quality, the model has to "reason" for every prompt proportional to the training inference.
This is arguably the case of diminishing returns being reached, as answer token prices saturate the willingness of customers to pay.
They've run into a wall.
The output tokens per task just exploded. From 118k tokens (46k Answer/71k Reasoning) in 5.1 to 274k tokens (81k Answer/192k Reasoning) in 5.2.
You have to figure city council who approved this are either idiots or getting bribes.
A city council member trying to balance a budget isn't engaging in corruption by choosing the option that reduces an expense in the city budget, even if it just places the cost on the people paying for parking instead. Constituents would be more likely to complain about higher property taxes or cuts to city services than to complain about a fee like this.
Maybe they just got bribed, but that seems less likely.
Then aside from theories of corrupt decision making, why wouldn’t every city or parking provider choose the $0 option? (Particularly city governments with a responsibility to their residents.)
Born on January 12, 1917 in Munich, Felix emigrated from Germany in 1933, shortly after Hitler came to power, and settled with part of his family in his mother's native Florence; after obtaining his Italian high-school degree ("licenza liceale") he went on to study engineering at the Istituto Politecnico in Milan, but when the Fascists' anti-semitic laws of 1938 prohibited Jews from enrolling in public schools and universities, he settled in Paris, again with part of his family. At the outbreak of WWII in September 1939, Felix was in Switzerland and a return to France was impossible; in 1940 he emigrated to Chile before finally settling in Berkeley to join his brother Bernard in 1941, and enrolling in the engineering school of the University of California. From 1943 to 1946 he served in the US Army and became one of "The Ritchie Boys" - GIs of German origin who spoke German natively and were trained in Military Intelligence at Camp Ritchie, Maryland. He was discharged with the rank of Master Sergeant and returned to the University of California to study architecture; after having obtained his MA he became assistant to Eric Mendelsohn, the renowned architect who had recently joined Berkeley's Architecture Department.
https://www.legacy.com/us/obituaries/legacyremembers/felix-r...
We had the original book when I was a kid. My wife gave me a copy (off of AbeBooks or somewhere) a few years ago and I was a bit overcome with emotion at seeing it again.
> I messed with tons of "world record distance" designs as a kid
Please comment with any feedback you have regarding the site. I hope to improve its existing features and to add additional features in the future.
https://www.foldableflight.com/planes/mystic
Started watching the video not planning on actually making it, saw that it is done with A4 paper and grabbed a random sheet at my desk to follow along. The pocket felt like a nice "a-ha!" moment. As someone who only knew the "naive" way to make paper airplanes from A4 paper, this is the best performing and prettiest paper airplane I've made in my life! It almost feels like it's not real how smoothly it stays straight in the air compared to all my paper airplanes in childhood.
Edit: Tried making the flapping wings AeroDactyl but it didn't work out :( wasn't aerodynamic and didn't flap its wings just went straight to the ground
Edit 2: Tried making the Jetstream (another 1 minute plane) and it came out well! Mine is INCREDIBLY asymmetrical and still flies better than any other plane I've made other than the Mystic!
Edit 3: Tried making the Advanced Elanus and I made it! But it's a little shoddy and much tougher for sure. Looks cool but it doesn't glide anywhere near as good as in the video (I guess you really need to perfect it.)
Final edit: My planes :) https://i.imgur.com/xnMdzJv.jpeg

21.jul.2023 https://news.ycombinator.com/item?id=36784032 25 comments
26.may.2023 https://news.ycombinator.com/item?id=36087442 76 comments
18.jul.2022 https://news.ycombinator.com/item?id=32134691 96 comments
06.dec.2021 https://news.ycombinator.com/item?id=29466325 8 comments
16.jun.2020 https://news.ycombinator.com/item?id=23545860 8 comments
18.oct.2018 https://news.ycombinator.com/item?id=18249755 206 comments
Max, streamed (128K cap): 128,000 tokens, $2.56, empty file, in September and today.
Max, Batch API (300K): 255,957 tokens for $2.56 in September, 243,707 for $2.44 today. The two drawings: https://playcode.io/marketing/assets/static/claude-opus-5-5-... and https://playcode.io/marketing/assets/static/claude-opus-5-5-...
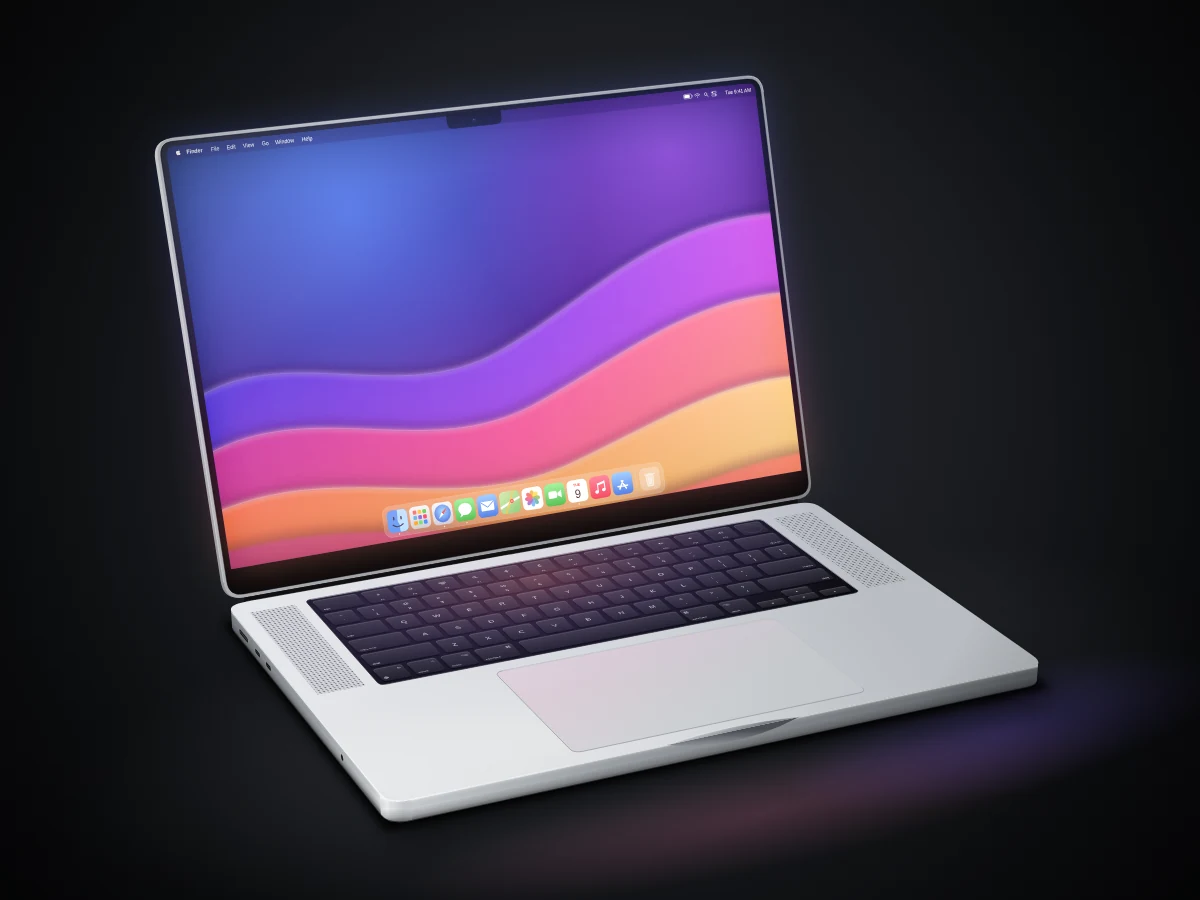
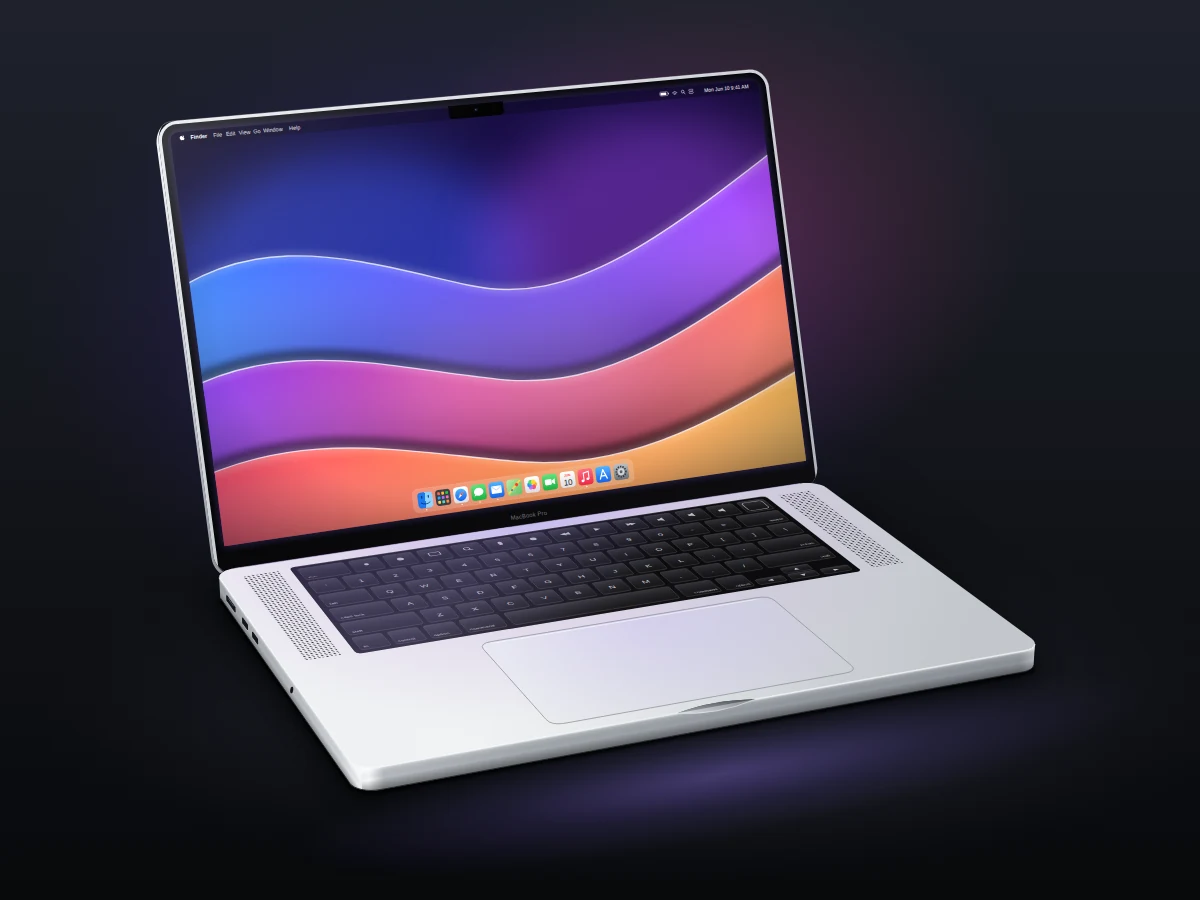
Xhigh: 86,096 tokens for $1.72 in September, 107,333 for $2.15 today.
The Batch API bills half price. Max ran out of the 128K ceiling again, to the token. Given 300K, it drew the same kind of laptop with 5% fewer tokens. Xhigh used 25% more and drew the same kind of laptop. That's inside the noise: 17 identical calls at high ranged from 17,757 to 59,705 tokens.
The model is still the best of everything we've tried. Most likely the next best would be Fable 5.2. But we don't like Fable because essentially the result is the same, just the price is higher. Its medium and high are close to what Opus 5.5 Max had, but the price is higher.
(I run Playcode, an AI app builder. We benchmark every model before we add it.)
And then Sam Altman is gonna sue your ass for owning a measuring cup.
If I order a 16oz beer and get a 12oz pour, I'm going to call it out.
I worked recently for a German megacorp, for whatever reason they gave us unlimited access to a bunch of models, up to sonnet 4.5/Gpt o1 etc, so not the best or latest models. And no agentic tools.
So I built a custom Claude Code clone because they exposed the api from their custom 'LLM Chat' clone in the client and accepted my user credentials for access.
Essentially a frankenstein AI harness using various models for their strengths, including using the OpenAI best model for memory context consolidation and compaction + Sonnet as orchestrator, etc. I was able to spawn 20+ agents to do my work and basically automate my entire job at that corp. I think my internal bill was something like 5k euros per month and I was being careful to not abuse it...
It was better than the best you could get from claude at the time (about a year ago now I think), in terms of task performance completion.
So imagine what someone with essentially infinite spend can do with endless fable agents. AKA US government and Anthropic internal.
If you're selling model capabilities for money, and you change the mobile capabilities, not changing the model designator (name and/or version number) is fraud, full stop.
If you calculate Elo only before 11/3 and compare to only after 11/3, the Elo is 52 points lower after. Unfortunately we are still in beta so this isn’t conclusive (confidence interval of -160 to +40).
If we do this calculation on all our models, Opus 5.5 is first in apparent drop. (Again, not definitive, but supports the conclusion.
Every time a new model drops it feels wildly powerful, then regresses to some sort of generic SOTA level we've been used to over the last 6 months.
I remember my first coding prompt with, I think it was sonnet 4.6, on a fresh account and it was shocking how much it successfully did off a single prompt - I haven't found that with any other model at any other time and I suspect it was because they put me at the top of the priority list to get a "wow" reaction.
Regression after a release is pretty well-agreed upon, but I'm wondering if they secretly have a huge amount in the tank they aren't releasing. Either as a card to play in the future, or because they can't keep up with demand. I've heard anecdotes of people working in these companies saying that the public models aren't even close to their actual capabilities... Anyone have any opinion on this?
It is something I also appreciate with some of the other labs like deepseek who publish the checkpoint they are running on and still sell you the old one for a period of time as well.
Its obnoxiously anticonsumer to be constantly chopping and changing what a model represents on customers who are paying them an awful lot more to be on the frontier models.
The only one I'm familiar with testing Opus 5.5 specifically over time is https://github.com/ninjahawk/livenerf and it's not showing anything.
The Windows Insider program has shown plenty of people will willingly sign up to be testers for a taste of the rawhide. Anthropic could do this in a transparent way but they continue to choose not too.
Opus is suddenly fumbling basic tool calls and failing to finish tasks even at high, where I had been permanently using it on low effort with success since it came out. It is very frustrating.
My guess is they quantized it and/or reallocated DC capacity to train a new model, this has happened before.
* nerf them based on supply and demand, when you have a high demand, nerf it, but keep charging same price.
* do you want to show revenue growth to investors? increase thinking tokens, customers will keep paying, because again, this is non-deterministic system, sometimes it thinks more
* do you want to increase profits? start serving 4-bit, 5-bit quantizations and keep charging same price
* want even more? publish a paper "Advanced Auto Super Smart Prompt Router - AASSPiRation", and start routing requests to Qwen3.8-27B or GemmaE2B from time to time on the edge
* Not enough? introduce "Complex Chained Workflows - CCW" in your coding harness, which spawns multiple deterministic workflows (which you can't stop or control) and they will use Haiku to write the code, then use Opus 5.5 high to verify the code (which is obviously wrong) and Opus 5.5 produces recommendations on how to fix the code, delegates to Haiku, which again fails writing proper code, and keep doing it 5-6 times, you made lots and lots of money (don't forget, all should run in parallel, to pick one best result among 10 outputs).
https://www.reddit.com/r/ClaudeCode/comments/1xr9x5y/the_ner...
Now it's like talking to my hungover self, after 3 days bender, who just wanted to be left alone.
Totally possible that I'm just hallucinating/projecting/etc or my workflows somehow changed in terms of difficulty, but it's been kind of shocking.
Of all the reasons to look at local inference, this is the one which pushes me in that direction the most. I want to rely on a model for consistency in my workflows. If I wake up on Monday and suddenly it's refactoring things it built on Friday, that's a huge problem. That makes it unreliable.
This is the #1 thing i HATE with LLMs. They are not predictable like a compiler is.
Tonight has been maddening with the kinds of absurd mistakes it's repeatedly making. It's so frustrating.
I'm the kind of person that wants something to be consistent and reliable. And Anthropic has been great, except for in this way. Which is enough of a recurring frustration (about every couple months this year) that I genuinely can't wait for other options to catch up. Then I'll be leaving as soon as I can.
I just don't know how long that will be.
Edit: tried it, and it’s definitely not better for this use case. e-means wins by needing fewer passes over a huge dataset, but relaxing a mesh on a sphere has no dataset: each Voronoi cell’s centroid can be computed directly from its geometry. Mini-batches just swap that for a noisy sampled estimate of the same thing. It has the same objective and the same optimum, so at best it matches Lloyd. In practice it was much slower and left the grid noisy, and with small sample budgets it even tangled the mesh.
[1] https://webgcm.app/explain/grid#nudging-the-cells-into-shape
That's impressive!
I'm also available via: @gmail.com
(please don't write code with `@whitespace` as I get a lot of GitHub notifications)